

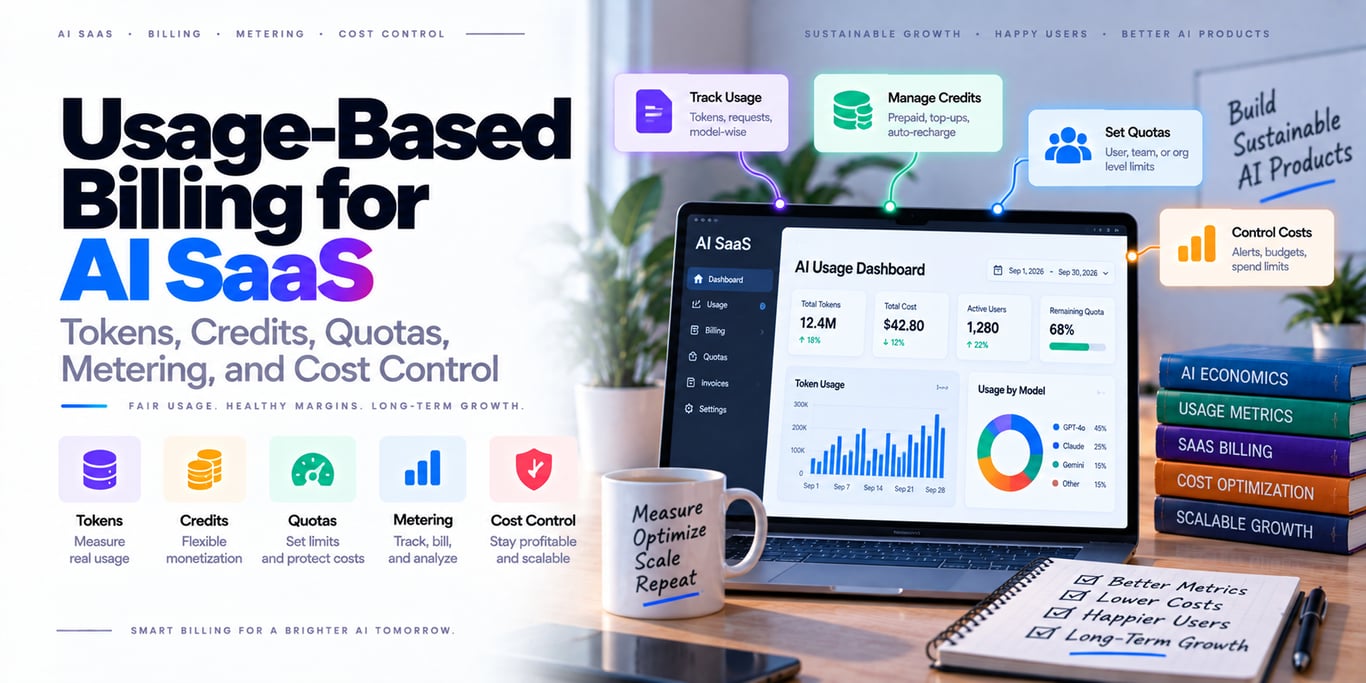
Usage-Based Billing for AI SaaS: Tokens, Credits, Quotas, Metering, and Cost Control
A production guide to AI SaaS usage-based billing: separate provider cost from customer pricing, meter tokens and tools correctly, build auditable credit ledgers, enforce quotas and reservations, handle retries, and reconcile invoices.
AI Backend
Showing 11 of 11 articlesModel Serving in Production: Batching, Autoscaling, GPU Efficiency, and LLM Inference
A production guide to model serving covering dynamic and continuous batching, KV cache, prefix caching, speculative decoding, quantization, multi-GPU inference, autoscaling, rollouts, and observability.
Backend for AI Agents: Durable Runs, Tool Execution, Memory, Safety, and Observability
A production backend blueprint for AI agents covering durable run state, tool execution, MCP, idempotency, approvals, memory, cancellation, sandboxing, budgets, recovery, observability, and agent evaluations.
RAG Backend Architecture: Ingestion, Hybrid Retrieval, Reranking, Security, and Evals
A production RAG backend guide covering ingestion, parsing, chunking, metadata and ACLs, hybrid retrieval, reranking, context assembly, citations, prompt-injection defenses, evaluation, and observability.
Qdrant for Production Vector Search: Filtering, Hybrid Retrieval, and Scaling
A practical production guide to Qdrant covering HNSW search, payload filtering, hybrid dense+sparse retrieval, quantization, multitenancy, sharding, snapshots, and embedding migrations.
Milvus in Production: Architecture, Indexes, Hybrid Search, and Scaling
A production-focused guide to Milvus covering architecture, vector indexes, hybrid search, consistency, schema design, multi-tenancy, embedding migrations, and when a dedicated vector database is actually worth operating.
Pinecone in Production: Serverless Vector Search, RAG, Namespaces, and Cost
A production-focused guide to Pinecone serverless vector search covering RAG, namespaces for multi-tenancy, dense+sparse retrieval, reranking, eventual consistency, costs, backups, and embedding migrations.
Weaviate in Production: Hybrid Search, Vector Indexes, Multi-Tenancy, and RAG
A production guide to Weaviate covering hybrid vector + BM25F search, HNSW/Flat/Dynamic/HFresh indexes, ACORN filtering, multi-tenancy, reranking, compression, and RAG retrieval design.
Backend Architecture for AI Applications: Models, Data, Queues, Caching, Safety, and Evals
A production backend architecture guide for AI applications covering model gateways, structured outputs, streaming, files, queues, retrieval, caching, quotas, safety, multi-tenancy, observability, evals, and controlled model rollouts.

Building AI API Infrastructure: Gateways, Streaming, Tool Calls, Rate Limits, and Observability
A production architecture guide for AI API gateways covering multi-provider routing, typed streaming, tool calls, structured outputs, quotas, retries, usage accounting, fallbacks, and observability.
Vector Databases Explained: Indexes, Filtering, Hybrid Search, and When You Need One
A practical guide to vector databases covering exact vs ANN search, HNSW and IVF indexes, metadata filtering, hybrid lexical+semantic search, multi-tenancy, embedding migrations, and when a dedicated vector database is actually needed.