

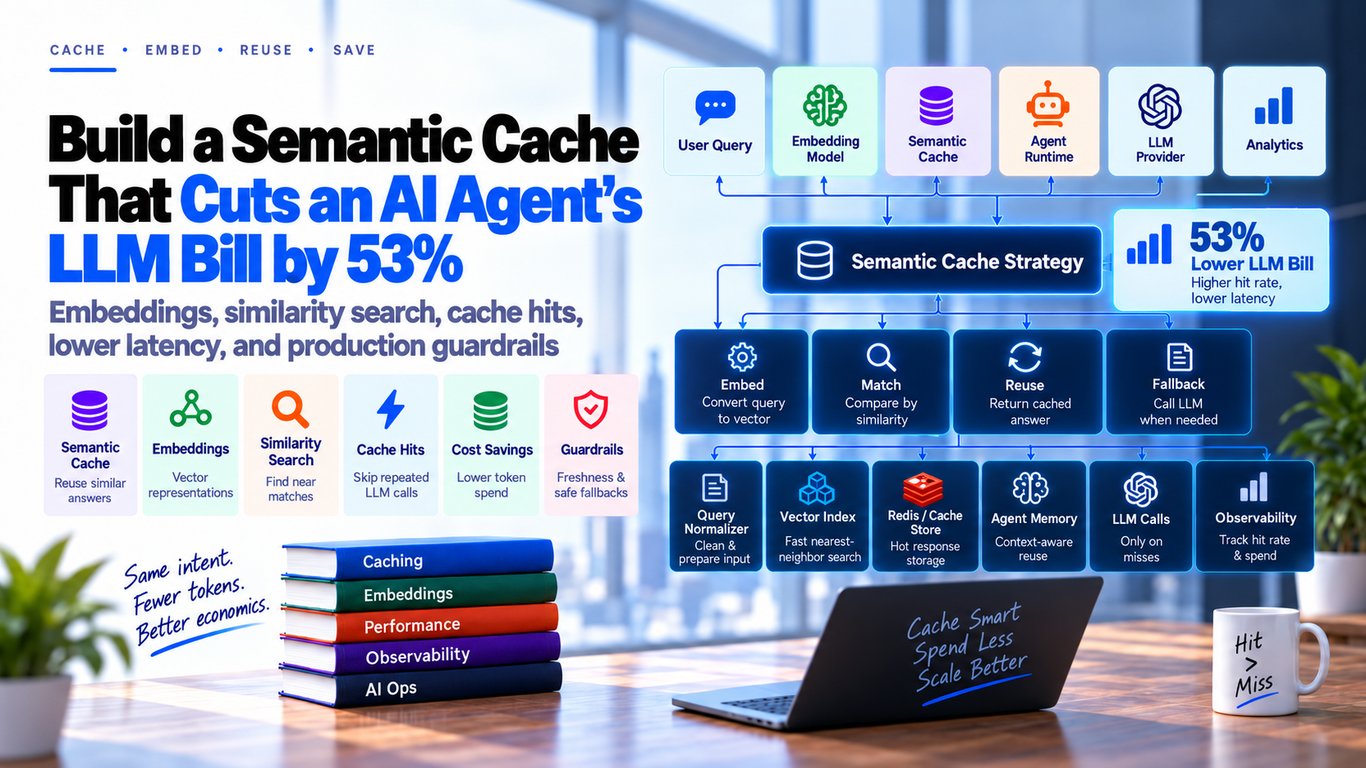
A practical Python guide to semantic response caching with ChromaDB, local MiniLM embeddings, and Gemini.
A semantic cache reuses an earlier answer when a new question is sufficiently similar in meaning. For repetitive support traffic, that can eliminate unnecessary LLM requests, lower response latency, and reduce inference costs—provided the cache does not return the wrong answer or reuse stale information.
In the demonstration described here, 60 customer questions across 15 intents are replayed with and without caching. With a similarity threshold of 0.82, the cache serves 32 of 60 questions, leaving 28 LLM calls instead of 60 and producing approximately 53% lower model cost for that test sequence.
Table of Contents
- What You're Building
- Architecture Overview
- Prerequisites & Setup
- Config
- The Store Policy and a Day of Questions
- One Gemini Call, With a Price Tag
- The Semantic Cache
- The Agent: Cache First, LLM on a Miss
- Choosing the Threshold From Data
- The Report and the Chart
- The Command Line
1. What You're Building
Customer support agents repeatedly answer the same questions. Someone asks, “What's the return window?” and a different customer asks the same thing with slightly different wording. Without caching, the agent pays for another LLM request to generate substantially the same answer.
A semantic cache sits in front of the LLM. It converts an incoming question into an embedding—a numeric representation of its meaning—and checks whether a previously answered question is sufficiently similar. If a fresh match is found, the agent returns the saved answer immediately. Otherwise, it calls the LLM and stores the new question-answer pair.
The example uses a fictional home-decor store, Kumkum Home, and compares 60 questions with the cache disabled and enabled. Its reported results are:
| Metric | No cache | Semantic cache |
|---|---|---|
| Customer questions | 60 | 60 |
| LLM calls | 60 | 28 |
| Questions served from cache | 0 | 32 |
| Model cost | ~$0.0095 | ~$0.0045 |
| Model cost reduction | — | ~53% |
| Example cache-hit latency | — | ~6 ms |
| Example LLM latency | ~900–1,000 ms | ~900–1,000 ms on misses |
The key engineering problem is avoiding incorrect matches: “Can I cancel my order?” and “Can I cancel my subscription?” sound similar but require different answers. A reliable semantic cache must balance its hit rate against false matches and stale information.
2. Architecture Overview
Customer question
       |
       v
Embed locally with all-MiniLM-L6-v2
       |
       v
Find nearest cached question in ChromaDB
       |
       +-- Similarity >= 0.82, current policy, not expired
       |             |
       |             v
       |      Return cached answer
       |
       +-- Similarity below threshold, stale, or not found
                     |
                     v
                  Call Gemini
                     |
                     v
             Save question + answer
                     |
                     v
                 Return answer
Each incoming question is embedded locally using all-MiniLM-L6-v2. ChromaDB searches previously stored question embeddings, using cosine distance. The cache hit decision depends on the similarity threshold, time-to-live (TTL), and policy version.
A cached answer may become stale in three ways:
- TTL expiry: the entry is too old.
- Policy version change: the business rules used to generate the entry have changed.
- Targeted invalidation: a particular fact changes and related cached answers must be deleted.
3. Prerequisites & Setup
You need Python 3.12 or newer, the uv Python package manager, and a Gemini API key.
Create the project and install the demonstrated dependencies:
uv init semantic-cache --python 3.12
cd semantic-cache
uv add chromadb==1.5.9 google-genai==2.29.0 matplotlib==3.11.2 python-dotenv==1.2.4
mkdir src
Remove the starter main.py created by uv init; the application modules will live in src/.
Create a .env file at the project root:
GEMINI_API_KEY=your_key_here
Create .gitignore:
.env
.venv/
__pycache__/
*.pyc
.cache/
*.png
ChromaDB includes an ONNX build of the all-MiniLM-L6-v2 embedding model. On the first use, it downloads the embedding assets into Chroma's local cache (about 80 MB in the example), so the demonstration does not require a separate PyTorch model installation.
Command note: Commands later in this guide use PYTHONPATH=. so imports such as from src.cache import ... resolve. For PowerShell, use $env:PYTHONPATH="." once per terminal instead of the Unix-style prefix.
4. Config
All shared settings live in one file. The most important are:
THRESHOLD: minimum cosine similarity required to reuse an answer.TTL_SECONDS: how long an existing answer remains eligible for reuse.MIN_INTERVAL_S: spacing between Gemini requests in the demonstration.
The demonstration models paid-tier cost using $0.30 per million input tokens and $2.50 per million output tokens, even when using an API tier with free requests. These are the example's pricing assumptions, not a live pricing feed.
Save as src/config.py:
"""Settings for the semantic cache demo.

Inputs: GEMINI_API_KEY from .env.
Outputs: constants used by every other module (model, prices, threshold, paths).
"""

import os
import sys
from pathlib import Path

from dotenv import load_dotenv

ROOT = Path(__file__).resolve().parent.parent
load_dotenv(ROOT / ".env")

# Some Windows consoles default to a non-UTF-8 encoding.
sys.stdout.reconfigure(encoding="utf-8")

GEMINI_API_KEY = os.getenv("GEMINI_API_KEY", "")
MODEL = "gemini-3.5-flash-lite"

# The example spaces requests to respect its stated free-tier rate limit.
MIN_INTERVAL_S = 4.2

# Illustrative paid-tier USD prices per 1M tokens.
PRICE_IN_PER_M = 0.30
PRICE_OUT_PER_M = 2.50

# Only reuse cached answers when similarity clears this value.
THRESHOLD = 0.82

# Expire entries after one day.
TTL_SECONDS = 24 * 60 * 60

CACHE_DIR = ROOT / ".cache"
COLLECTION = "answers"
The 0.82 threshold is chosen from the sample traffic in section 9. It should not be treated as a universal threshold for unrelated datasets, embedding models, or policies.
5. The Store Policy and a Day of Questions
To make cache savings measurable, every LLM call answers using the same small store policy. Each request sends the policy text again; a cache hit avoids paying for that repeated context and the generated answer.
The policy includes placeholders for its version and return window. Invalidation demonstrations can later change the return window from 7 to 10 days without maintaining multiple independent policy copies.
Save as src/traffic.py:
"""The store policy and a day of customer questions.

Inputs: none (all data is inline).
Outputs: POLICY and TRAFFIC, a list of (question, intent) pairs in arrival
order. Intent tags grade cache accuracy; the agent never sees them.
"""

POLICY = """Kumkum Home - customer support policy (version {version})

Returns: unused items can be returned within {return_days} days of delivery.
Custom-stitched items cannot be returned.
Refunds: prepaid orders are refunded to the original payment method within
5-7 working days of the return reaching our warehouse. COD orders are
refunded by bank transfer (NEFT) within 7-10 working days, after you share
your bank details.
Cancellation: an order can be cancelled free of charge until it is dispatched.
After dispatch, refuse the parcel at the door instead.
Subscriptions: the monthly candle box subscription can be cancelled anytime
from My Account > Subscriptions; the current month's box still ships.
Cash on delivery: available for orders up to Rs 5,000. A Rs 49 COD fee applies.
Delivery: metro cities in 2-4 days, other locations in 5-7 days. Free shipping
above Rs 999.
Warranty: brass and copper items carry a 1-year warranty against manufacturing
defects.
Exchange: size or colour exchange is free, once per order, within the return
window.
Damaged items: report damage within 48 hours of delivery with a photo of the
parcel.
Gift wrap: available for Rs 50 per item at checkout.
Contact: support@kumkumhome.in, 10am-7pm IST, Monday to Saturday.
"""

# (question, intent). Some questions are paraphrases; others sound similar
# but have different answers (for example, order vs subscription cancellation).
TRAFFIC: list[tuple[str, str]] = [
    ("How many days do I have to return an item?", "returns_window"),
    ("Can I cancel my order?", "cancel_order"),
    ("What is the return window?", "returns_window"),
    ("How long does delivery take?", "delivery_time"),
    ("Is cash on delivery available?", "cod_limit"),
    ("When will I get my refund for a prepaid order?", "refund_prepaid"),
    ("How many days to return a product?", "returns_window"),
    ("How do I cancel my candle subscription?", "cancel_subscription"),
    ("Is there a warranty on brass items?", "warranty"),
    ("I want to cancel my order, how?", "cancel_order"),
    ("How long will delivery take to my city?", "delivery_time"),
    ("When do I get my refund for a COD order?", "refund_cod"),
    ("Can I return something after a week?", "returns_window"),
    ("Do you charge extra for cash on delivery?", "cod_fee"),
    ("Is shipping free?", "free_shipping"),
    ("My item arrived damaged, what do I do?", "damaged"),
    ("can i cancel the order.", "cancel_order"),
    ("Can I exchange for a different size?", "exchange"),
    ("What is the return window for items?", "returns_window"),
    ("Do brass products come with a warranty?", "warranty"),
    ("How long does a prepaid refund take?", "refund_prepaid"),
    ("Do you offer gift wrapping?", "gift_wrap"),
    ("How do I cancel my order?", "cancel_order"),
    ("How can I contact customer support?", "contact"),
    ("How many days for delivery?", "delivery_time"),
    ("What is the maximum order value for cash on delivery?", "cod_limit"),
    ("How many days do I get to return an item?", "returns_window"),
    ("The product came broken. What should I do?", "damaged"),
    ("How do I stop my subscription?", "cancel_subscription"),
    ("What is the delivery time?", "delivery_time"),
    ("Can I return a custom stitched item?", "returns_custom"),
    ("Is there a fee for COD?", "cod_fee"),
    ("I want to cancel my order", "cancel_order"),
    ("Is shipping free on my order?", "free_shipping"),
    ("How long does it take to refund a COD order?", "refund_cod"),
    ("What's your return window?", "returns_window"),
    ("Can I exchange an item for a different colour?", "exchange"),
    ("How long will delivery take?", "delivery_time"),
    ("Is there a warranty on copper items?", "warranty"),
    ("Can I cancel my subscription?", "cancel_subscription"),
    ("When will I receive my refund for a prepaid order?", "refund_prepaid"),
    ("What are your customer support hours?", "contact"),
    ("Can I cancel my order?", "cancel_order"),
    ("Item arrived damaged, what should I do?", "damaged"),
    ("Do you have gift wrap?", "gift_wrap"),
    ("How many days do I have to return an item?", "returns_window"),
    ("Is cash on delivery available for my order?", "cod_limit"),
    ("Delivery time to a small town?", "delivery_time"),
    ("Is there any extra charge for cash on delivery?", "cod_fee"),
    ("When will my refund come for a COD order?", "refund_cod"),
    ("Can I exchange it for another size?", "exchange"),
    ("Is shipping free?", "free_shipping"),
    ("Can I return an item after a week?", "returns_window"),
    ("How do I reach customer support?", "contact"),
    ("How can I cancel my order?", "cancel_order"),
    ("Do brass items have a warranty?", "warranty"),
    ("How long does delivery take?", "delivery_time"),
    ("Can I return custom stitched items?", "returns_custom"),
    ("What is the return window?", "returns_window"),
    ("How long does a prepaid refund take?", "refund_prepaid"),
]
Check the traffic size and distinct intents:
PYTHONPATH=. uv run python -c "from src.traffic import TRAFFIC; print(len(TRAFFIC), len({i for _, i in TRAFFIC}))"
60 15
There are 60 questions but only 15 distinct intent labels. Thus, 45 questions repeat an earlier intent, putting the theoretical hit ceiling at 75% for this arrival order. A cache can fail to reach that ceiling when semantically equivalent questions receive embeddings that are too far apart, and it can return an incorrect answer when different intents receive embeddings that are too close together.
The intent labels are used only to grade the offline experiment; they are not supplied to the agent when it answers a question.
6. One Gemini Call, With a Price Tag
To measure savings, each LLM call must report its token usage, estimated dollar cost, and latency. Gemini returns token-usage details in response.usage_metadata; the cost function applies the prices configured earlier.
The client is initialized only when an API key is present, allowing modules to import successfully before a real API call is attempted.
Save as src/llm.py:
"""One call to Gemini, with tokens, cost, and latency tracked.

Inputs: a customer question and the policy text to answer from.
Outputs: an Answer with reply, token counts, dollar cost, and latency.
"""

import asyncio
import time
from dataclasses import dataclass

from google import genai
from google.genai import errors, types

from src.config import (
    GEMINI_API_KEY,
    MIN_INTERVAL_S,
    MODEL,
    PRICE_IN_PER_M,
    PRICE_OUT_PER_M,
)

_client = genai.Client(api_key=GEMINI_API_KEY) if GEMINI_API_KEY else None

INSTRUCTIONS = (
    "You are the support agent for Kumkum Home. Answer the customer in one or two "
    "short sentences, using only the policy below.

"
)


@dataclass
class Answer:
    """A reply from the model and what it cost."""

    text: str
    in_tokens: int
    out_tokens: int
    cost: float
    latency_ms: float


def price(in_tokens: int, out_tokens: int) -> float:
    """Return the paid-tier dollar cost of one call."""
    return (in_tokens * PRICE_IN_PER_M + out_tokens * PRICE_OUT_PER_M) / 1_000_000


_last_call = 0.0


async def _pace() -> None:
    """Wait so calls start at least MIN_INTERVAL_S apart."""
    global _last_call
    wait = _last_call + MIN_INTERVAL_S - time.monotonic()
    if wait > 0:
        await asyncio.sleep(wait)
    _last_call = time.monotonic()


async def _generate(
    question: str, policy: str
) -> tuple[types.GenerateContentResponse, float]:
    """Send one request; retry on 429/503. Return response and latency in ms.

    Only a successful attempt is timed, so time spent pacing or waiting for
    a retry does not count as model latency in the comparison.
    """
    if _client is None:
        raise ValueError("GEMINI_API_KEY is not set - add it to .env")

    config = types.GenerateContentConfig(
        system_instruction=INSTRUCTIONS + policy,
        thinking_config=types.ThinkingConfig(thinking_level="MINIMAL"),
    )

    for attempt in range(4):
        await _pace()
        start = time.perf_counter()
        try:
            response = await _client.aio.models.generate_content(
                model=MODEL, contents=question, config=config
            )
            return response, (time.perf_counter() - start) * 1000
        except errors.APIError as err:
            if err.code not in (429, 503) or attempt == 3:
                raise
            await asyncio.sleep(15)


async def answer(question: str, policy: str) -> Answer:
    """Ask the model one question and measure tokens, cost, and latency."""
    response, latency_ms = await _generate(question, policy)

    usage = response.usage_metadata
    in_tokens = usage.prompt_token_count or 0
    # Thinking tokens are also counted at the output price in this example.
    out_tokens = (usage.candidates_token_count or 0) + (usage.thoughts_token_count or 0)
    return Answer(
        text=(response.text or "").strip(),
        in_tokens=in_tokens,
        out_tokens=out_tokens,
        cost=price(in_tokens, out_tokens),
        latency_ms=latency_ms,
    )
Why the pacing matters
For the demonstrated free-tier setting, the script spaces calls by 4.2 seconds to avoid a burst of requests. It retries API errors 429 (rate limiting) and 503 (service overload) after waiting 15 seconds, up to four attempts.
The latency timer starts after the deliberate pacing wait, so a model call is measured independently of waiting for an API rate-limit slot. The calculation is deliberately scoped to inference cost, not the complete end-to-end runtime of the benchmark.
Try a single model call:
PYTHONPATH=. uv run python -c "import asyncio; from src.llm import answer; from src.traffic import POLICY; print(asyncio.run(answer('What is the return window?', POLICY.format(version=1, return_days=7))))"
The example response is a short policy-based answer, with a cost of approximately $0.00016 for one call and roughly one second of model latency. Actual token counts, cost, and timing vary by generated output and model availability.
7. The Semantic Cache
This is the core of the implementation. Each stored question is searched by meaning rather than exact text, while its cached answer and validity metadata are preserved.
A ChromaDB entry contains:
- Document: the original question, which is embedded and used for nearest-neighbour lookup.
- Metadata: the stored answer, policy version, and creation timestamp.
7.1 The Embedder
Using Chroma's ONNX-backed MiniLM embedding function, create one embedding model instance for the process and reuse it. The example also disables tokenizer padding. For individual short questions, this avoids doing unnecessary work on padding tokens and reduces the cost of local embedding operations.
Start src/cache.py:
"""Semantic cache: reuse an answer when a new question means the same thing.

Inputs: questions embedded locally by the MiniLM ONNX model.
Outputs: a Hit with the cached answer and its similarity, or None on a miss.
Entries carry the policy version and a timestamp so stale ones can be dropped.
"""

import time
import uuid
from dataclasses import dataclass

import chromadb
from chromadb.utils.embedding_functions import ONNXMiniLM_L6_V2

from src.config import CACHE_DIR, COLLECTION, THRESHOLD, TTL_SECONDS

# Reuse a single embedder throughout the process.
EMBEDDER = ONNXMiniLM_L6_V2()
# Embed individual questions without fixed-size padding.
EMBEDDER.tokenizer.no_padding()
In the demonstrated environment, using a single model instance and removing padding can bring a local lookup down from hundreds of milliseconds to around 6 ms. The exact performance will depend on the model, CPU, input length, and data size.
Because different questions then have different token-sequence lengths, the sample embeds one question per call rather than stacking differently sized sequences into a single unpadded batch.
7.2 Opening the Cache
ChromaDB's PersistentClient saves the data under .cache/ so entries survive application restarts. Cosine space lets the cache interpret Chroma's reported distance as similarity = 1 − distance.
Add the following to src/cache.py:
@dataclass
class Hit:
    """A cached answer that is close enough to reuse."""

    answer: str
    question: str
    similarity: float
    age_s: float


class SemanticCache:
    """Question-to-answer store, looked up by meaning instead of exact text."""

    def __init__(
        self, threshold: float = THRESHOLD, ttl_s: float = TTL_SECONDS
    ) -> None:
        """Open (or create) the cache on disk."""
        self.threshold = threshold
        self.ttl_s = ttl_s
        client = chromadb.PersistentClient(path=str(CACHE_DIR))
        self.col = client.get_or_create_collection(
            COLLECTION,
            embedding_function=EMBEDDER,
            configuration={"hnsw": {"space": "cosine"}},
        )
7.3 Lookup
A lookup asks Chroma for the single closest cached question among entries written for the current policy version. It then checks two conditions:
- TTL: an expired entry is deleted when encountered (lazy eviction).
- Threshold: the best match must be sufficiently similar or it counts as a miss.
Add this method inside SemanticCache:
    def lookup(self, question: str, policy_version: int) -> Hit | None:
        """Return the closest fresh entry if it clears the threshold, else None."""
        if self.col.count() == 0:
            return None

        result = self.col.query(
            query_texts=[question],
            n_results=1,
            where={"policy_version": policy_version},
        )
        if not result["ids"][0]:
            return None

        similarity = 1 - result["distances"][0][0]
        meta = result["metadatas"][0][0]
        age_s = time.time() - meta["created_at"]
        if age_s > self.ttl_s:
            # Expired; evict so the next answer can be stored freshly.
            self.col.delete(ids=result["ids"][0])
            return None
        if similarity < self.threshold:
            return None
        return Hit(meta["answer"], result["documents"][0][0], similarity, age_s)
Policy version filtering prevents answers written under an older business policy from being treated as current after the policy changes.
7.4 Store, Targeted Invalidation, and Clear
A cache miss results in a fresh LLM answer. The store method saves that answer under its originating question. Only the question is embedded; the answer lives in metadata.
When a policy fact changes, invalidate_similar can delete questions semantically close to a description of the changed topic instead of discarding unrelated answers. Its threshold is intentionally broader than the answer-reuse threshold, because deleting a few extra entries is safer than keeping a wrong cached answer.
Add these methods inside SemanticCache:
    def store(self, question: str, answer: str, policy_version: int) -> None:
        """Save a fresh answer under the question it was generated for."""
        self.col.add(
            ids=[uuid.uuid4().hex],
            documents=[question],
            metadatas=[{
                "answer": answer,
                "policy_version": policy_version,
                "created_at": time.time(),
            }],
        )

    def invalidate_similar(
        self, topic: str, min_similarity: float = 0.5
    ) -> list[str]:
        """Delete entries whose questions are close to a topic; return them."""
        if self.col.count() == 0:
            return []
        result = self.col.query(
            query_texts=[topic], n_results=self.col.count()
        )
        doomed = [
            (entry_id, question)
            for entry_id, question, distance in zip(
                result["ids"][0], result["documents"][0], result["distances"][0]
            )
            if 1 - distance >= min_similarity
        ]
        if doomed:
            self.col.delete(ids=[entry_id for entry_id, _ in doomed])
        return [question for _, question in doomed]

    def clear(self) -> None:
        """Remove every entry."""
        ids = self.col.get()["ids"]
        if ids:
            self.col.delete(ids=ids)
Test the cache locally without spending LLM tokens:
PYTHONPATH=. uv run python -c "
from src.cache import SemanticCache
c = SemanticCache(threshold=0.0); c.clear()
c.store('Can I cancel my order?', 'Until dispatch', 1)
for q in ['How do I cancel my order?', 'Can I cancel my subscription?', 'How do I stop my subscription?']:
    print(round(c.lookup(q, 1).similarity, 3), q)
c.clear()
"
An example of the distinction:
0.895 How do I cancel my order?
0.693 Can I cancel my subscription?
0.413 How do I stop my subscription?
The reworded order-cancellation question scores 0.895, while a similar-sounding subscription-cancellation question scores 0.693. A threshold of 0.82 separates those examples, but the real question is how it performs across the full test set.
8. The Agent: Cache First, LLM on a Miss
The agent connects the cache to Gemini. On a hit, it returns the cached answer with zero additional LLM cost; on a miss, it calls Gemini, stores the returned answer, and includes both lookup and model time in the request's measured latency.
Passing cache=None disables caching so the benchmark can measure the same workflow as a baseline.
Save as src/agent.py:
"""The support agent: check the cache first; call the LLM only on a miss.

Inputs: a question, the cache, and the current policy (text + version).
Outputs: a Record describing the hit/miss, cost, and latency.
"""

import time
from dataclasses import dataclass

from src.cache import SemanticCache
from src.llm import answer


@dataclass
class Record:
    """One answered question and what it cost."""

    question: str
    answer: str
    hit: bool
    cost: float
    latency_ms: float
    similarity: float = 0.0
    matched: str = ""


async def ask(
    question: str,
    policy: str,
    version: int,
    cache: SemanticCache | None,
) -> Record:
    """Answer one question, from the cache when possible."""
    lookup_ms = 0.0
    if cache is not None:
        start = time.perf_counter()
        hit = cache.lookup(question, version)
        lookup_ms = (time.perf_counter() - start) * 1000
        if hit is not None:
            return Record(
                question, hit.answer, True, 0.0, lookup_ms,
                hit.similarity, hit.question
            )

    reply = await answer(question, policy)
    if cache is not None:
        cache.store(question, reply.text, version)

    # A miss pays for both the lookup and the model call.
    return Record(
        question, reply.text, False, reply.cost,
        lookup_ms + reply.latency_ms
    )
Important correctness boundary: This cache is appropriate only for answers that should be shared across the intended audience. Generic policy questions can often be cached safely. An account-specific question such as “Where is my order?” must not return tracking details from another customer's cached response. Per-user or per-tenant access rules must be part of the cache key or enforced outside the shared cache.
9. Choosing the Threshold From Data
The threshold is the most important decision in a semantic cache:
- Set it too low, and different questions can receive the same incorrect answer.
- Set it too high, and valid paraphrases are missed, causing unnecessary LLM calls.
Instead of choosing a threshold by intuition, replay real traffic against an empty cache at several thresholds and measure both cache hits and wrong-answer hits. A false hit means that a cached question and the incoming question carry different intent labels.
Arrival order matters: only previously missed questions enter the cache. A question can be answered incorrectly if a similar but different-intent question is already stored.
Save as src/sweep.py:
"""Pick a similarity threshold from data instead of guessing one.

Inputs: TRAFFIC, with questions and their known intents.
Outputs: cache hits and false hits for each threshold, including the most
similar question pair with different intents.

The sweep embeds questions locally and replays the cache in memory.
"""

from dataclasses import dataclass

import numpy as np

from src.cache import EMBEDDER
from src.traffic import TRAFFIC


@dataclass
class SweepPoint:
    """The result of replaying the traffic at one threshold."""

    threshold: float
    hits: int
    false_hits: int
    example: str = ""


def similarity_matrix(questions: list[str]) -> np.ndarray:
    """Embed questions and return pairwise cosine similarities."""
    # Embed one at a time: lengths vary when tokenizer padding is disabled.
    vectors = np.array([EMBEDDER([question])[0] for question in questions])
    vectors = vectors / np.linalg.norm(vectors, axis=1, keepdims=True)
    return vectors @ vectors.T


def replay(sims: np.ndarray, threshold: float) -> SweepPoint:
    """Replay traffic through an empty cache; count hits and false hits."""
    intents = [intent for _, intent in TRAFFIC]
    cached: list[int] = []
    point = SweepPoint(threshold, 0, 0)
    for i, (question, intent) in enumerate(TRAFFIC):
        best = max(cached, key=lambda j: sims[i, j], default=None)
        if best is None or sims[i, best] < threshold:
            cached.append(i)
            continue
        point.hits += 1
        if intents[best] != intent:
            point.false_hits += 1
            point.example = point.example or (
                f'"{question}" got the answer to "{TRAFFIC[best][0]}" '
                f'({sims[i, best]:.2f})'
            )
    return point


def closest_wrong_pair(sims: np.ndarray) -> tuple[float, str, str]:
    """Find the most similar pair of questions asking different things."""
    best = (0.0, "", "")
    for i, (qi, ii) in enumerate(TRAFFIC):
        for j, (qj, ij) in enumerate(TRAFFIC[:i]):
            if ii != ij and sims[i, j] > best[0]:
                best = (float(sims[i, j]), qi, qj)
    return best


def sweep(
    thresholds: list[float],
) -> tuple[list[SweepPoint], tuple[float, str, str]]:
    """Replay at each threshold; return results and closest wrong pair."""
    sims = similarity_matrix([question for question, _ in TRAFFIC])
    return [replay(sims, t) for t in thresholds], closest_wrong_pair(sims)
Interpreting the threshold sweep
The example's 60-question replay produces the following reported results:
| Similarity threshold | Cached hits | Hit rate | False hits |
|---|---|---|---|
| 0.50 | 45 | 75% | 9 |
| 0.55 | 43 | 72% | 6 |
| 0.60 | 43 | 72% | 5 |
| 0.65 | 40 | 67% | 3 |
| 0.70 | 38 | 63% | 3 |
| 0.75 | 38 | 63% | 2 |
| 0.80 | 35 | 58% | 0 |
| 0.82 | 32 | 53% | 0 |
| 0.85 | 29 | 48% | 0 |
| 0.90 | 26 | 43% | 0 |
| 0.95 | 18 | 30% | 0 |
At 0.50, the cache captures all 45 repeat intents, but 9 answers are wrong. An incoming prepaid-refund question can incorrectly receive an order-cancellation answer.
At 0.80, the replay has no false hits in this arrival order and 35 cache hits (58%). However, the most similar pair of different-intent questions scores approximately 0.819:
“Is there any extra charge for cash on delivery?”
“Is cash on delivery available?”
Because these questions ask different things, reversing their order could cause an incorrect answer at a threshold of 0.80. Raising the threshold just above that pair gives the chosen 0.82.
At 0.82, the test reports 32 cache hits (53%) with no false hits. The remaining difference between the 75% theoretical ceiling and the observed hit rate is partly due to embedding-model limitations: for instance, “How many days do I have to return an item?” and “What is the return window?” can receive surprisingly different vectors.
Practical rule: Calibrate the threshold against known different-intent pairs, not only the overall hit rate. Repeat this evaluation as query patterns, policies, and embedding models change.
10. The Report and the Chart
The reporting module turns the baseline and cached runs into a side-by-side totals table, a cumulative model-cost chart, and a per-question latency chart.
The example uses median latency instead of average latency because a single unusually slow LLM call could distort the average. The chart uses orange for the baseline and blue for the cache-enabled run.
matplotlib.use("Agg") enables PNG generation without a graphical window.
Save as src/report.py:
"""Turn two replay runs into numbers and charts.

Inputs: Records from one run without the cache and another with it.
Outputs: a printed totals table and cache_report.png (cost and latency).
"""

import statistics
from pathlib import Path

import matplotlib

matplotlib.use("Agg")  # Write PNG files; never open an interactive window.
import matplotlib.pyplot as plt

from src.agent import Record

NO_CACHE = "#eb6834"
CACHE = "#2a78d6"
INK = "#52514e"
GRID = "#e4e3df"


def totals(records: list[Record]) -> dict:
    """Sum one run: LLM calls, dollars, and median latency."""
    return {
        "calls": sum(not r.hit for r in records),
        "cost": sum(r.cost for r in records),
        "p50_ms": statistics.median(r.latency_ms for r in records),
        "hit_p50_ms": statistics.median(
            [r.latency_ms for r in records if r.hit] or [0]
        ),
    }


def print_totals(plain: list[Record], cached: list[Record]) -> float:
    """Print the side-by-side table; return the percentage of cost saved."""
    a, b = totals(plain), totals(cached)
    saved = 100 * (1 - b["cost"] / a["cost"])
    per_100k = 100_000 / len(plain)

    print(f"
{'':22}{'no cache':>14}{'with cache':>14}")
    print(f"{'LLM calls':22}{a['calls']:>14}{b['calls']:>14}")
    print(
        f"{'cost (paid tier)':22}"
        f"{('$' + format(a['cost'], '.5f')):>14}"
        f"{('$' + format(b['cost'], '.5f')):>14}"
    )
    print(
        f"{'cost per 100k questions':22}"
        f"{('$' + format(a['cost'] * per_100k, '.2f')):>14}"
        f"{('$' + format(b['cost'] * per_100k, '.2f')):>14}"
    )
    print(
        f"{'median latency':22}"
        f"{a['p50_ms']:>12.0f}ms{b['p50_ms']:>12.0f}ms"
    )
    print(
        f"{'median cache hit':22}"
        f"{'-':>14}{b['hit_p50_ms']:>12.0f}ms"
    )
    print(
        f"
Cost saved: {saved:.0f}% "
        f"({len(plain) - b['calls']} of {len(plain)} answered from cache)"
    )
    return saved


def _style(ax: plt.Axes, title: str, ylabel: str) -> None:
    """Recessive grid and axes, left-aligned title."""
    ax.set_title(title, loc="left", fontsize=12, color="#0b0b0b")
    ax.set_xlabel("question # (arrival order)", color=INK)
    ax.set_ylabel(ylabel, color=INK)
    ax.grid(axis="y", color=GRID, linewidth=0.8)
    ax.tick_params(colors=INK)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)


def plot_cost(
    ax: plt.Axes, plain: list[Record], cached: list[Record]
) -> None:
    """Cumulative model spend, question by question, with and without cache."""
    xs = range(1, len(plain) + 1)
    for records, color, label in (
        (plain, NO_CACHE, "no cache"),
        (cached, CACHE, "with cache"),
    ):
        running, total = [], 0.0
        for r in records:
            total += r.cost
            running.append(total * 1000)  # milli-dollars are easier to read
        ax.plot(xs, running, color=color, linewidth=2, label=label)
        ax.annotate(
            f"{label}  ${total:.4f}", (len(records), running[-1]),
            xytext=(-4, 6), textcoords="offset points", ha="right", color=INK
        )
    _style(ax, "Cumulative LLM cost", "cost (milli-dollars, paid tier)")
    ax.legend(frameon=False, loc="upper left")


def plot_latency(
    ax: plt.Axes, plain: list[Record], cached: list[Record]
) -> None:
    """Latency of each request; cache hits sit far lower on a log scale."""
    xs = range(1, len(plain) + 1)
    ax.scatter(
        xs, [r.latency_ms for r in plain],
        s=18, color=NO_CACHE, label="no cache"
    )
    ax.scatter(
        xs, [r.latency_ms for r in cached],
        s=18, color=CACHE, label="with cache"
    )
    ax.set_yscale("log")
    _style(ax, "Latency per question", "milliseconds (log scale)")
    ax.legend(frameon=False, loc="center right")


def save_chart(
    plain: list[Record], cached: list[Record], saved: float, path: Path
) -> None:
    """Draw both panels side by side and save a PNG."""
    fig, (left, right) = plt.subplots(
        1, 2, figsize=(13, 5), facecolor="#fcfcfb"
    )
    plot_cost(left, plain, cached)
    plot_latency(right, plain, cached)
    fig.suptitle(
        f"Semantic cache: {saved:.0f}% cheaper on {len(plain)} support questions",
        x=0.01, ha="left", fontsize=15, fontweight="bold"
    )
    fig.tight_layout()
    fig.savefig(path, dpi=150)
    plt.close(fig)
Reading the two plots
Cumulative cost: The orange line shows total model spend as all 60 questions go to the LLM. The blue line grows more slowly whenever a cache hit avoids a paid request. Both lines initially rise together because the cache starts empty; the separation represents cumulative savings.
Latency: A log-scale chart makes the separation visible between cache hits in the single-digit millisecond range and model calls that take hundreds or thousands of milliseconds. A linear chart would compress the cache-hit points near zero.
The two metrics are intentionally plotted separately because dollars and milliseconds are different quantities.
11. The Command Line
The command-line module connects the individual components. The documented commands are:
| Command | Purpose |
|---|---|
ask "question" | Answer one question through the persistent semantic cache. |
replay | Run all questions without caching, then again with an initially empty cache; print totals and save a chart. |
sweep | Compare cache-hit and false-hit counts across several similarity thresholds without making LLM calls. |
invalidate-demo | Demonstrate a stale answer and three invalidation approaches. |
clear | Remove all entries from the persistent cache. |
In the example, sweep runs locally without paid model calls. replay performs 88 Gemini calls—60 for the no-cache baseline and 28 for cache misses—and may take approximately 7 minutes with rate-limit pacing. The documented invalidation demonstration requires another 6 model calls.
The initial src/main.py code shown below handles the imports, single-line progress output, the replay pipeline, and the beginning of threshold-sweep setup:
"""Command line for the semantic cache demo.

Commands:
    ask "question"     answer one question through the persistent cache
    replay             run traffic without, then with, the cache; totals + chart
    sweep              hits vs false hits at each threshold (free, no LLM calls)
    invalidate-demo    show a stale answer, then three ways to get rid of it
    clear              empty the cache
"""

import argparse
import asyncio

from src.agent import Record, ask
from src.cache import SemanticCache
from src.config import ROOT, THRESHOLD
from src.report import print_totals, save_chart
from src.sweep import sweep
from src.traffic import POLICY, TRAFFIC

POLICY_V1 = POLICY.format(version=1, return_days=7)


def show(n: int, record: Record) -> None:
    """Print one line per question: what happened, how long it took."""
    if record.hit:
        how = f'HIT  {record.similarity:.2f} ~ "{record.matched}"'
    else:
        how = "MISS -> LLM"
    print(f"{n:>3}  {record.latency_ms:>7.0f} ms  {how:<58} {record.question}")


async def run_traffic(cache: SemanticCache | None) -> list[Record]:
    """Send every question in TRAFFIC through the agent, in order."""
    records = []
    for n, (question, _) in enumerate(TRAFFIC, start=1):
        record = await ask(question, POLICY_V1, 1, cache)
        show(n, record)
        records.append(record)
    return records


async def cmd_replay() -> None:
    """Same traffic, cache off vs cache on (starting empty)."""
    print("=== Pass 1: no cache - every question calls the LLM ===")
    plain = await run_traffic(None)

    print(f"
=== Pass 2: semantic cache, threshold {THRESHOLD} ===")
    cache = SemanticCache()
    cache.clear()
    cached = await run_traffic(cache)
    saved = print_totals(plain, cached)
    path = ROOT / "cache_report.png"
    save_chart(plain, cached, saved, path)
    print(f"Chart saved to {path.name}")


def cmd_sweep() -> None:
    """Show what each threshold buys and what it risks."""
    thresholds = [round(0.50 + 0.05 * i, 2) for i in range(10)]
BUILDING AN AI PRODUCT?
Talk to Lofingo about custom autonomous AI agents, enterprise workflow automation, and scalable software systems.
EXPLORE AI SERVICES →