

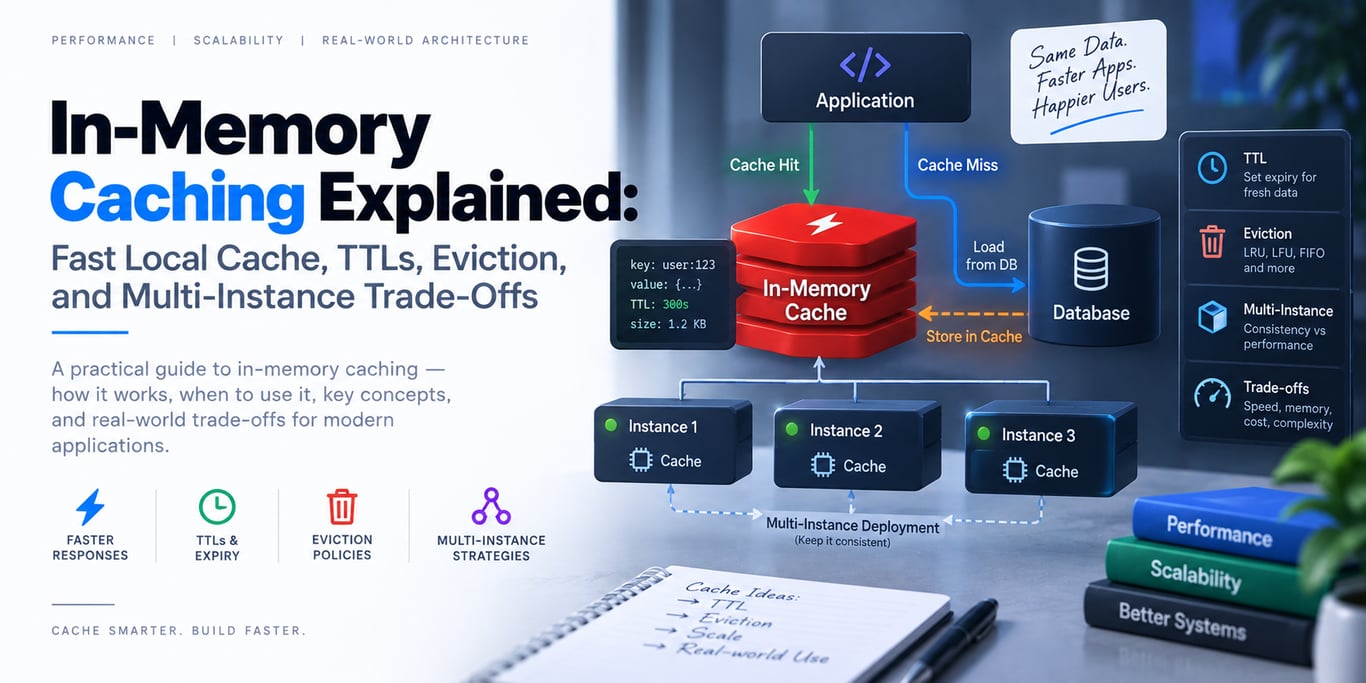
In-Memory Caching Explained: Fast Local Cache, TTLs, Eviction, and Multi-Instance Trade-Offs
A practical in-memory cache guide covering zero-network-hop local caching, TTLs, size-based eviction, memory limits, process restarts, cache stampedes, and the consistency trade-offs of multi-instance applications.
Scalability
Showing 13 of 18 articles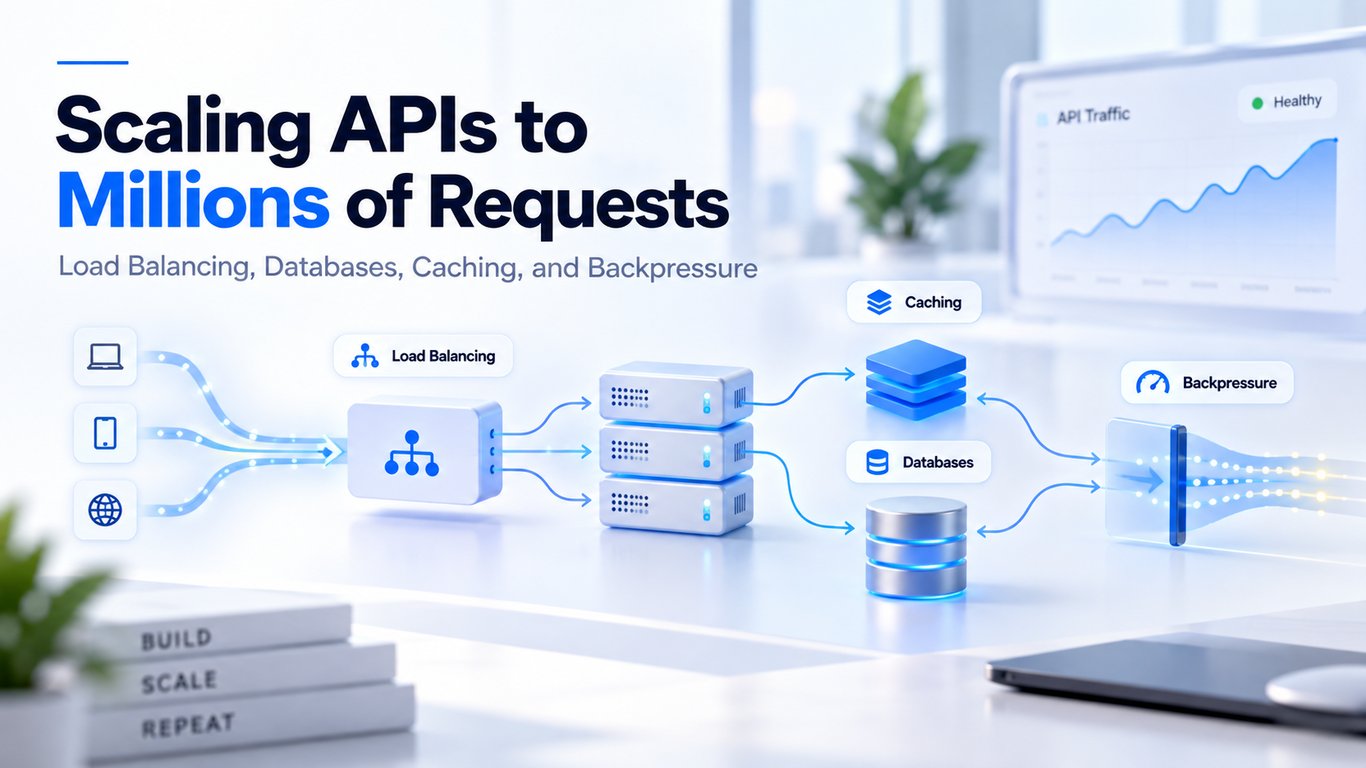
Scaling APIs to Millions of Requests: Load Balancing, Databases, Caching, and Backpressure
A practical guide to scaling high-traffic APIs with stateless replicas, load balancing, database optimization and pooling, caching, queues, autoscaling, rate limits, backpressure, and tail-latency monitoring.
Backend Scalability Explained: Vertical vs Horizontal Scaling, Bottlenecks, and Elasticity
A clear introduction to backend scalability covering vertical vs horizontal scaling, stateless services, elasticity and autoscaling, bottleneck analysis, database limits, queues/caches, and how to measure real scaling efficiency.
Cache Invalidation Strategies: TTLs, Delete-on-Write, Versioned Keys, and Event-Driven Purges
A concise cache-invalidation guide covering TTLs, delete-on-write cache-aside, versioned keys, event-driven invalidation, targeted CDN purges, read/write races, and freshness trade-offs.
Horizontal vs Vertical Scaling: Which One Should You Use and When?
A practical comparison of horizontal vs vertical scaling covering performance, failure domains, stateless vs stateful workloads, distributed-system complexity, database scaling, and why most real systems use both.
Horizontal Scaling Explained: Stateless Replicas, Autoscaling, and Shared Bottlenecks
A practical horizontal-scaling guide covering stateless API replicas, horizontally scaled workers, autoscaling signals, session affinity, database and shared-state bottlenecks, downstream capacity, and failure-domain placement.

Why Caching Matters: Lower Latency, Less Database Load, and Better Scalability
A beginner-friendly explanation of why caching matters: cache hits and misses, lower latency, reduced database/origin load, browser/CDN/application/distributed cache layers, good cache candidates, freshness trade-offs, and useful metrics.

Load Balancing Explained: Algorithms, Health Checks, Layer 4/7, and Connection Draining
A concise load-balancing guide covering Layer 4 vs Layer 7, round-robin, least-connections/outstanding-request and hash-based algorithms, health checks, connection draining, failure domains, and sticky-session trade-offs.
How Netflix Scales: CDN Locality, Service Isolation, Data Platforms, and Reliability Lessons
Practical scaling lessons from Netflix's public engineering architecture: localize bandwidth with Open Connect, separate control and data planes, scale workloads independently, reduce repeated work, isolate failures, and invest in operational ownership.

Scaling with Caching: Cache-Aside, Hot Keys, Stampede Protection, and Multi-Layer Caches
A concise production guide to scaling with caching covering cache-aside, CDN/local/distributed cache layers, TTLs, invalidation, cache stampedes, hot keys, negative caching, cache-failure protection, and hit-ratio monitoring.
Types of Caching Explained: Browser, CDN, Local, Distributed, and Database Caches
A clear guide to browser, CDN/edge, reverse-proxy, local in-memory, distributed, and database caches—what each layer solves, where it lives, and how to choose the simplest useful cache.

HAProxy in Production: Layer 4/7 Load Balancing, Health Checks, TLS, and Traffic Control
A practical HAProxy guide covering frontends/backends, Layer 4 vs Layer 7 modes, health checks, round-robin and least-connections balancing, TLS termination, stick-table traffic controls, HA, and observability.
When Adding More Servers Actually Helps: A Practical Horizontal Scaling Checklist
A practical checklist for adding application servers safely: stateless replicas, health-aware load balancing, failure domains, database connection multiplication, autoscaling headroom, shared bottlenecks, and load-test validation.